Comparisons
ExpertEdge vs Udemy Business for enterprise learning
A side-by-side of Udemy Business and ExpertEdge for enterprise learning content: what each does well, where each falls short, and how to choose.
Oli Huggins
CEO and Founder
For data engineers
You learn this job by building pipelines. For the model underneath them, learn from the experts who wrote the book on it. From $10 a month.
Free for 7 days. Valid card required. Cancel anytime.
Sound familiar?
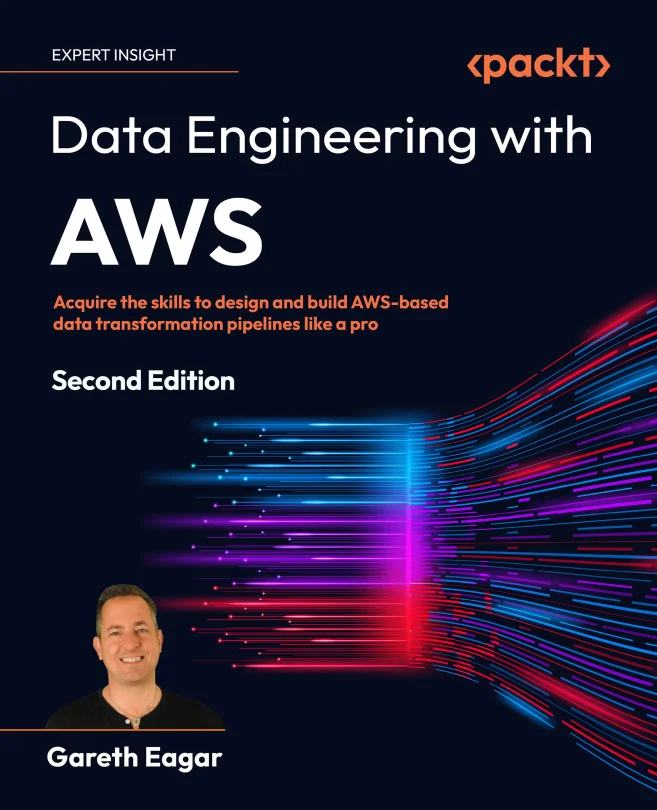
Your source did, at 2am. Keep building your own pipelines. When one breaks, our experts have already written the chapter on why.
it's really hard to get actually messy sets that model real-life sets
data/orders.csv
1,000 rows. Same columns every run.
sources/shop.orders
dbt run failed: column "customer_id" does not exist
Renamed upstream
In the tutorial
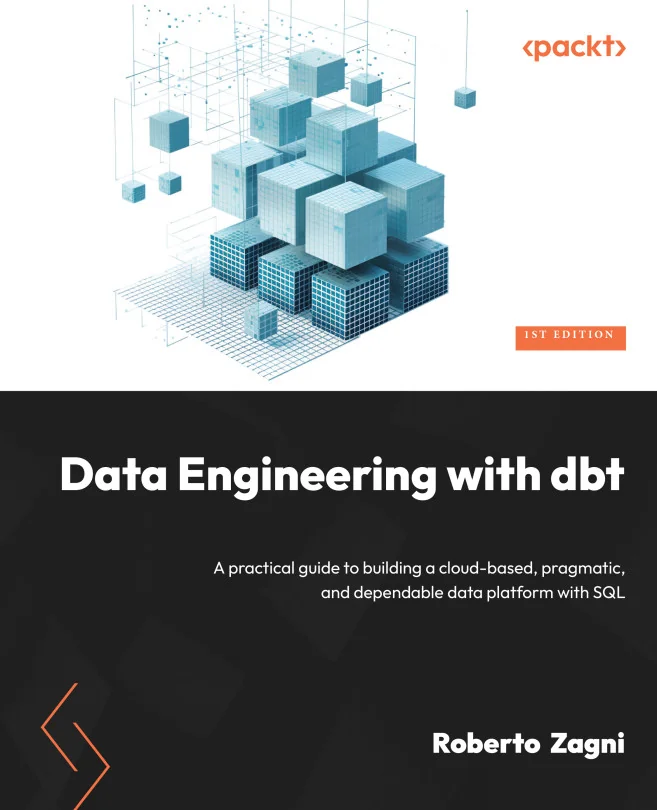
The sample file kept its columns. Nobody showed you how to hold the source team to theirs.
In ExpertEdge
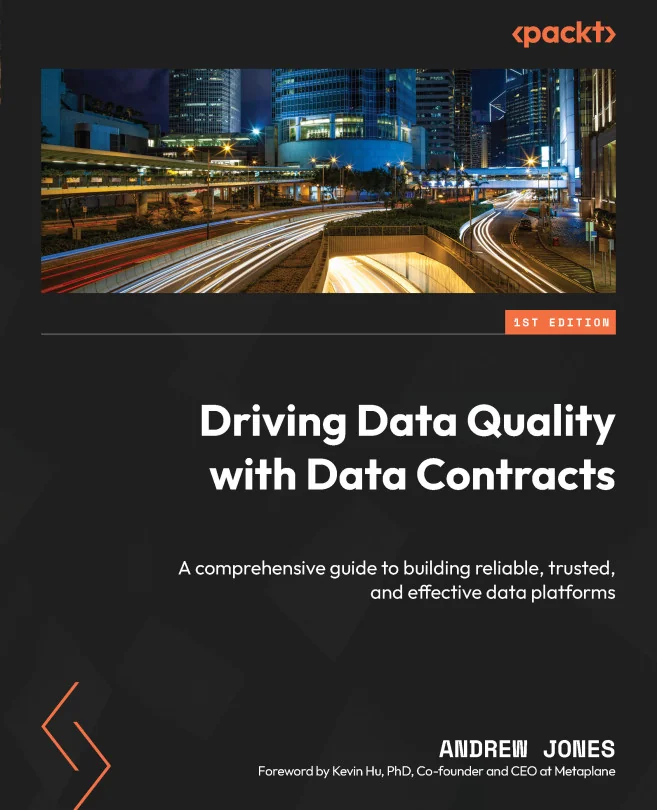
Andrew Jones wrote the book on data contracts. A contract stops the rename before it ships.
Retyped overnight
In the tutorial
The tutorial knew its schema. Your job guessed the types. It guessed wrong.
In ExpertEdge
Gláucia Esppenchutz's cookbook shows how to set a schema in PySpark instead of letting it guess.
Half null, no warning
In the tutorial
The course data had no gaps to find. You heard about this one from the dashboard team.
In ExpertEdge
Data Observability for Data Engineering shows you how to catch it before anyone opens a report.
What do the tutorials skip?
Tool tutorials stop at the pipeline. You're the one asked to fix the model nobody owns. Each fix below is a chapter of The Data Warehouse Toolkit, in the library now.
dim_customer
dim_dateShared by every fact
3dim_product
dim_store
fct_order_linesGrain: one order line
1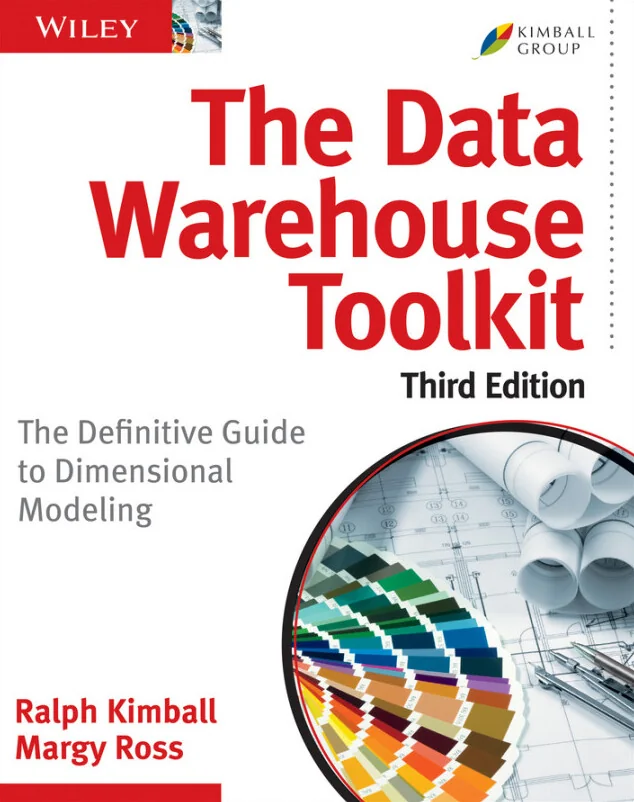
Chapter 3 · Retail SalesDeclare the grain before the first column. The four-step design starts there.
Chapter 5 · ProcurementThe customer moved city. Slowly changing dimensions keep both addresses.
Chapter 4 · InventoryOne date table for every fact. The bus matrix keeps it conformed.
Chapter 19 · ETL Subsystems and TechniquesThe order landed before its customer. Kimball gives late-arriving data its own subsystem.
18titles on data modelling, warehouses and lakehouses
Nearly 90%of data engineers report problems with their data modelsJoe Reis, 2026 State of Data Engineering, 1,101 respondents
Who wrote it?
Our experts wrote the standard texts on modelling, dbt and data contracts. You'll find them all in one library.
Is it current?
Every title carries the year it came out. Here's how many cover each platform you get hired to run, counted when this page was built.
worksheets/is_it_current.sql
-- run on the ExpertEdge catalogue when this page was builtselect platform,count(*) as titles,count_if(year >= 2024) as since_2024,max_by(title, released) as newestfrom expertedge.librarywhere category = 'Data Engineering & Analytics'group by platformorder by since_2024 desc;
7 rows
86data engineering and analytics titles released since January 2024
What do I read next?
Tutorials jump from Spark to Kafka to dbt and never say why. Set Data Engineer as your target. ExpertEdge lines up the skills it asks for and the courses behind each one.
What you've built
Where you are
Analytics Engineering
Data Governance & Quality
Data Ingestion & Transformation (ETL)
Data Modeling & Database Design
Data Warehousing & Big Data
Database Technologies & Administration
Real-Time & Stream Processing
Data Engineer
The goal
And the bootcamp?
A data engineering bootcamp can cost $2,500. The same money buys decades of the whole library here.
One data engineering bootcamp
$2,500
Price quoted on r/dataengineering, December 2024
What's the catch?
No cohort and no instructor. You read when the pipeline needs it.
No sandbox and no timer. You build on your own cloud account.
No forum or Q&A thread. Your team and the dbt Slack do that job.
We won't explain what a join is. Most titles start past the basics.
Keep building your own pipelines. The chapter on what breaks them is already here.
One price, everything included
Billed monthly
$15per month
Everything, month to month. Cancel anytime.
What's included
Billed yearly ($120)
$10per month
Everything for a third less, paid once a year.
What's included
No setup fees, no minimum seats. Invoicing available on plans of 20+ seats or more.
Comparing options? Read how ExpertEdge stacks up against Udemy Business, LinkedIn Learning, Coursera and edX in our comparisons
Our blog
Still not convinced ExpertEdge is the right fit for you? Review some of our thinking on enterprise learning, content strategy and more. See if we align via the full blog.
A side-by-side of Udemy Business and ExpertEdge for enterprise learning content: what each does well, where each falls short, and how to choose.
Oli Huggins
CEO and Founder
Enterprise L&D teams have approached content procurement the wrong way for a decade. What a mature B2B learning content stack looks like, and the layers most enterprises are missing.
Oli Huggins
CEO and Founder
A side-by-side of Coursera, edX and ExpertEdge for enterprise learning content: what each does well, where each falls short, and how to choose.
Oli Huggins
CEO and Founder