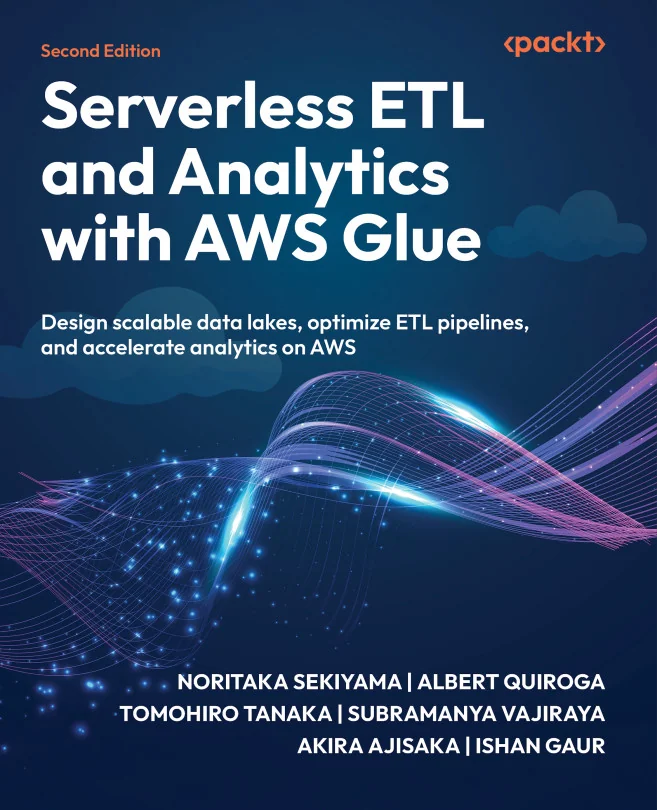
Serverless ETL and Analytics with AWS Glue
Design scalable data lakes, optimize ETL pipelines, and accelerate analytics on AWS
 +3
Created by Noritaka Sekiyama, Subramanya Vajiraya, Akira Ajisaka and 3 more
Learn how to build reliable, scalable data pipelines and analytics platforms using AWS Glue. Explore serverless ETL, data lake design, and cost optimization while mastering data ingestion, transformation, and security. Gain hands-on experience with real-world scenarios and practical workflows.
Packt | Aug 2026 | 532 min
What You Will Learn
You will start by exploring AWS Glue fundamentals before moving into hands-on data ingestion, transformation, and storage techniques. Step-by-step walkthroughs and practical code examples help you apply what you learn to real-world data lake scenarios. Along the way, you'll learn to monitor, tune, and troubleshoot workloads while integrating best practices for security and cost control.
Key Features
- Build and optimize serverless ETL pipelines using AWS Glue and Spark
- Secure, govern, and monitor data lakes with access controls and auditing
- Integrate open table formats for advanced analytics and efficient data management
Target Audience
Designed for data engineers, ETL developers, cloud architects, and analytics professionals working with AWS. If you want to improve pipeline reliability, governance, or cost efficiency in serverless data lakes, you'll benefit from this course. Some experience with AWS, Python, SQL, or Spark will help you get the most out of the material.