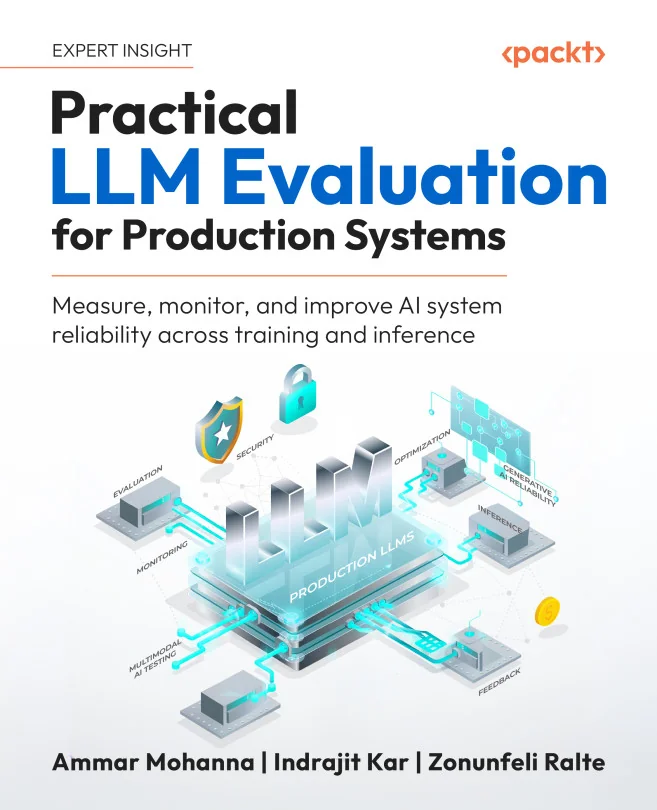
Practical LLM Evaluation for Production Systems
Measure, monitor, and improve AI system reliability across training and inference
 ZR
Created by Ammar Mohanna, Indrajit Kar, Zonunfeli Ralte
Learn how to measure and improve the reliability of AI systems in real-world production environments. Explore practical evaluation frameworks and metrics for LLMs, multimodal models, agents, and specialized AI applications. Move beyond benchmarks to build robust, enterprise-ready evaluation workflows.
Packt | Jun 2026 | 486 min
What You Will Learn
You will work through practical examples and real-world workflows to design and implement evaluation strategies for a range of AI systems. Each section guides you through connecting evaluation metrics to deployment gates, monitoring systems, and rollback criteria. By applying these methods, you will learn to manage non-determinism, validate tool use, and ensure production reliability.
Key Features
- Build evaluation frameworks for LLMs, multimodal, and agentic AI systems in production
- Measure quality, safety, and readiness using actionable metrics for real-world use cases
- Connect evaluation results to deployment, monitoring, and reliability decisions
Target Audience
This course is ideal for ML engineers, AI architects, data scientists, and technical leads responsible for deploying LLM-powered systems. If you have experience with machine learning, Python, and modern LLM concepts and want to measure reliability, safety, and operational readiness in production, you will find these skills directly applicable to your work.
Related courses