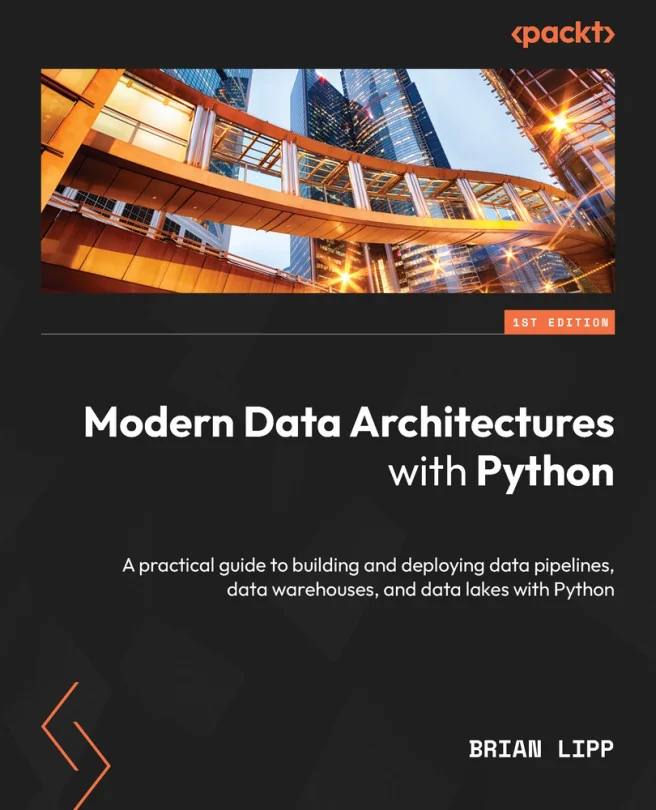
Modern Data Architectures with Python
A practical guide to building and deploying data pipelines, data warehouses, and data lakes with Python
Created by Brian Lipp
Explore how to design and build robust data pipelines, warehouses, and lakes using Python. Learn to integrate machine learning workflows and automate data processes with modern tools. Gain practical experience with open data platforms and key technologies like Apache Spark.
Packt | Sep 2023 | 318 min
What You Will Learn
You will start by working with Python and open data platforms to create and manage data pipelines. Step by step, you will use real-world tools like Databricks, Apache Spark, and Confluent Kafka to process data in both batch and streaming modes. Along the way, you will automate workflows and apply best practices for deploying and managing data resources.
Key Features
- Build and automate data pipelines with Python and open data platforms
- Apply medallion architecture and Delta Lake for scalable data solutions
- Integrate machine learning and MLOps into your data workflows
Target Audience
Ideal for data architects, engineers, and developers ready to advance their skills in building modern data ecosystems. If you have a basic understanding of Python and some experience with data, you will benefit from hands-on projects that help you design, automate, and scale data solutions for your organization.